Silent Until Broken: The Hidden Architecture of Workflow Failure
Photo: PV Nova (Paul-Victor Vettes), CC BY-SA 3.0, via Wikimedia Commons
There is a particular kind of organizational confidence that builds quietly over time. A workflow runs without incident for six months. Reports generate on schedule. Dashboards populate cleanly. And somewhere in the middle of all that apparent order, a small anomaly slips through unchecked—a mislabeled field, a broken lookup, a timestamp offset nobody noticed. For weeks, the system continues to run smoothly. Then, without warning, everything downstream is wrong.
This is not an edge case. It is one of the most common failure patterns in modern business operations, and it persists precisely because it is so easy to overlook until it is far too late.
The Speed-Validation Trade-Off Nobody Talks About
When organizations build or expand workflows, the pressure to deliver results quickly is rarely subtle. Timelines compress. Teams prioritize getting data moving over ensuring that data is trustworthy. Validation checkpoints—the logic gates that catch anomalies before they travel further into a system—get treated as optional enhancements rather than structural requirements.
The reasoning is understandable, if shortsighted. A validation layer that pauses a pipeline to flag unexpected values feels like friction. It slows throughput. In a sprint-driven environment, that friction is often the first thing removed when deadlines tighten.
What gets left behind is not just a safety mechanism. It is the organization's only reliable means of knowing when the data it depends on has quietly stopped being accurate.
The cost of that omission rarely surfaces immediately. That delay is precisely what makes it dangerous.
How Silent Failures Compound
Data quality failures do not typically announce themselves. They propagate. A single upstream error—say, a CRM field that begins accepting null values where a customer segment identifier should appear—does not trigger an alert. It simply flows forward. The records that depend on that field for routing now route incorrectly. The reports that aggregate those records now reflect a distorted picture. The decisions made from those reports carry that distortion forward into strategy.
By the time someone notices that quarterly retention figures look implausible, the original anomaly may be three or four system layers removed from the visible output. Tracing it back requires reconstructing a chain of events that nobody documented because nobody knew there was anything to document.
Consider a scenario common in mid-sized retail operations: an inventory management integration begins pulling product category codes from a vendor feed that has, without notification, changed its taxonomy. The codes still arrive. The pipeline still runs. But the mapping that once translated vendor codes to internal categories now silently misfires on roughly 12 percent of SKUs. Reorder thresholds trigger incorrectly. Purchasing decisions are made on distorted stock projections. By the time the discrepancy surfaces in a physical audit, the organization has spent three weeks executing against a flawed picture of its own inventory.
The workflow never stopped running. That was the problem.
Why Validation Gets Deprioritized
Beyond deadline pressure, there are structural reasons that validation infrastructure tends to atrophy. The most significant is visibility asymmetry: the benefits of a validation checkpoint are invisible when things are working correctly, while the cost of building and maintaining one is immediately apparent.
Teams that invest in robust data quality checks rarely receive credit for the failures they prevent. The pipeline that flags a schema change before it corrupts a downstream report simply... works. There is no incident. No post-mortem. No recognition. The team that skipped the validation layer, by contrast, eventually generates a high-visibility crisis that commands organizational attention—and, paradoxically, often receives more resources in response than the team that prevented the problem ever did.
This creates a perverse incentive structure. Preventing failure is invisible. Recovering from failure is demonstrable effort. Until organizations recognize and actively counter this dynamic, validation infrastructure will continue to be treated as expendable.
What Early-Warning Systems Actually Look Like
Effective data validation is not a single checkpoint. It is a layered architecture distributed across the workflow at the points where data is most likely to shift, degrade, or arrive in an unexpected state.
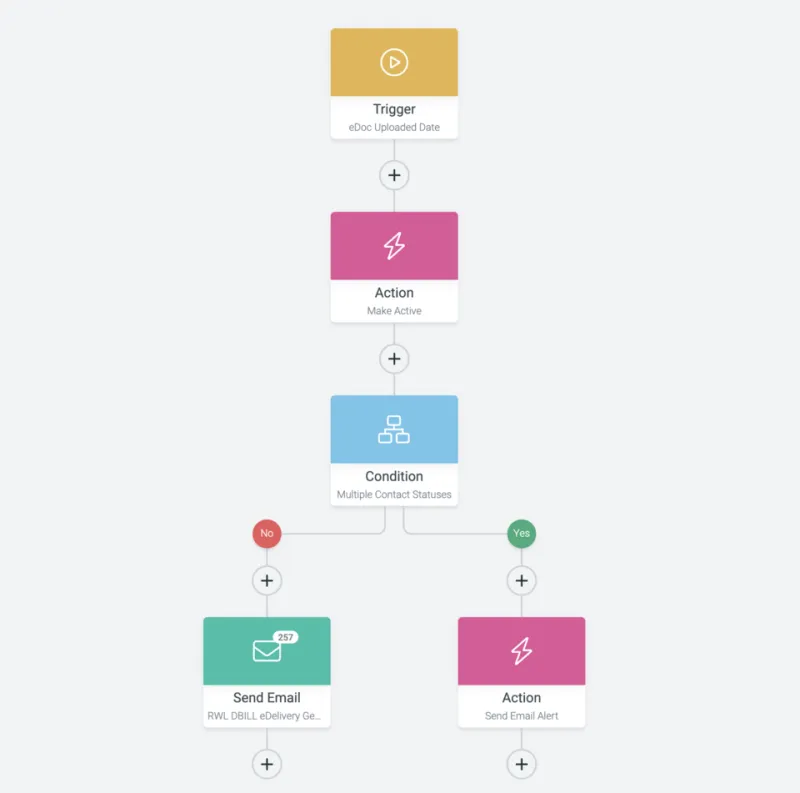
At the ingestion layer, this means schema validation that flags structural changes in incoming data before those changes propagate. A feed that previously delivered 14 columns and now delivers 13 should not silently continue processing. It should stop, surface the discrepancy, and require a deliberate acknowledgment before resuming.
At the transformation layer, statistical baseline monitoring adds a second line of defense. If a field that historically contains values between 50 and 500 suddenly begins producing values in the range of 5,000, that deviation should trigger a review—not because the value is necessarily wrong, but because it is unexpected enough to warrant confirmation before it influences a report or a model.
At the output layer, cross-validation against known reference points provides a final check. A revenue figure that contradicts a known prior-period benchmark by more than a defined threshold should be flagged before it reaches an executive dashboard, not after a CFO has already cited it in a board presentation.
None of these mechanisms are technically exotic. What makes them rare is organizational commitment—the decision to treat validation as a first-class component of workflow design rather than a quality-of-life enhancement to be added later.
The Cost of Corrective Work
Organizations that have experienced a significant silent failure tend to develop a sharper appreciation for prevention. The corrective work that follows a data quality incident is consistently more expensive than the validation infrastructure that would have prevented it.
In the inventory scenario described earlier, three weeks of corrective purchasing decisions, vendor communications, and internal reconciliation represented a cost that dwarfed what a schema change alert and category mapping review would have required. The same pattern repeats across finance, operations, marketing analytics, and customer data platforms. The failure is always cheaper to prevent than to repair—but the prevention cost is visible upfront, while the repair cost arrives as a surprise.
For organizations serious about data integrity, the question is not whether to invest in validation infrastructure. It is how to make that investment before the incident that would have made the case obvious.
Building a Culture That Catches Problems Early
Technology alone does not solve the validation vacuum. The organizations that consistently catch data quality problems early share a cultural characteristic: they treat anomalies as information rather than inconveniences.
When a flag fires and the data turns out to be fine, that is not a false alarm. It is confirmation that the system is functioning. When a flag fires and the data turns out to be corrupted, that is a successful catch—not a failure. Reframing validation alerts as operational intelligence, rather than pipeline interruptions, is the mindset shift that makes early-warning systems sustainable.
Workflows that run smoothly are worth protecting. The most reliable way to protect them is to assume they will eventually encounter conditions they were not built to handle—and to build the detection layer before that moment arrives, not after.